
NVIDIA NeMo Guardrails
NVIDIA NeMo Guardrails is an open-source toolkit for adding programmable guardrails to LLM-based conversational applications. Guardrails, or "rails" for short, are explicit ways of controlling what a model can do: staying off unwanted topics, following a predefined dialog path, enforcing a language style, masking sensitive data, or rejecting unsafe inputs and outputs. It is built around Colang, a small domain-specific language for defining flows, and is one of the most cited frameworks in the LLM security and safety space.
Key Features
- Five rail types: Input rails filter user input, dialog rails steer how the LLM is prompted, retrieval rails filter RAG chunks, execution rails check tool calls, and output rails filter model responses.
- Colang flows: Define conversational behavior in Colang files (
*.co) that read like pseudo-code, covering jailbreak checks, sensitive-data masking, fact self-checks, and moderation. - Vulnerability protection: Ships mechanisms for common LLM weaknesses such as jailbreaks and prompt injections, with an LLM vulnerability scanning evaluation workflow.
- Model-agnostic: Works with OpenAI models, Llama 2, and many others through a pluggable engine layer, plus optional LangChain integration.
- Async-first: Core mechanics use Python's async model, with both sync and async public APIs.
- Lightweight integration: Wrap an existing chat endpoint with
LLMRails.generatewhile keeping the OpenAI-compatible input and output format.
Use Cases
- RAG question answering: Enforce fact-checking and output moderation over retrieved documents.
- Domain-specific assistants: Keep chatbots on topic and following designed conversational flows.
- Production LLM endpoints: Add rails to custom LLM endpoints for safer customer interactions.
- Agent tool safety: Use execution rails to gate what tools and services an agent may call.
Pricing
NeMo Guardrails is free and open source under the Apache-2.0 license. You pay only for the underlying LLM API usage that your guarded application consumes.
Getting Started
- Install with
pip install nemoguardrails(Python 3.10 through 3.13). - Create a guardrails config directory with
config.ymland Colang*.cofiles. - Load the config and wrap your LLM call:
config = RailsConfig.from_path("PATH/TO/CONFIG"), thenrails = LLMRails(config). - Call
rails.generate(messages=.)with an OpenAI-compatible message list.
Frequently Asked Questions
What is Colang?
Colang is the small DSL NeMo Guardrails uses to define rails. A flow like define flow\n user express greeting\n bot express greeting reads almost like a spec, and predefined examples cover jailbreak checks and moderation.
Does it work with open-source models?
Yes. The engine layer is pluggable and supports models such as Llama 2 and others, in addition to OpenAI's API models.
Is NeMo Guardrails the same as a scanner?
No. NeMo Guardrails is a runtime control layer that sits between your app and the LLM. For finding vulnerabilities proactively, pair it with a scanner such as NVIDIA Garak.
Alternatives
- Garak: NVIDIA's LLM vulnerability scanner, used before deploying guardrails to find the holes.
- Llama Guard 3: A Meta classifier model for input and output moderation.
- Langfuse: Observability and evaluation for LLM applications, complementing runtime rails.
Tips & Best Practices
- Scan before you rail: Use Garak to discover weaknesses, then configure rails to block the common attack paths.
- Start minimal: Define one or two input and output rails first, then expand dialog and execution rails as you learn failure modes.
- Layer with permissions: Rails filter what the model says; separate access controls still gate what tools and data the application can reach.
Sources
Comments
No comments yet. Be the first to comment!
Related Tools


Related Insights

After I Connected Obsidian to OpenClaw, It Started Helping Me Make Decisions
Once Obsidian stopped being just a place to store notes and started working with OpenClaw, it began helping me organize context, connect information, and improve real decisions.
After Code Stopped Being Scarce (Part II): From AI Writing Code to AI Taking Part in Delivery
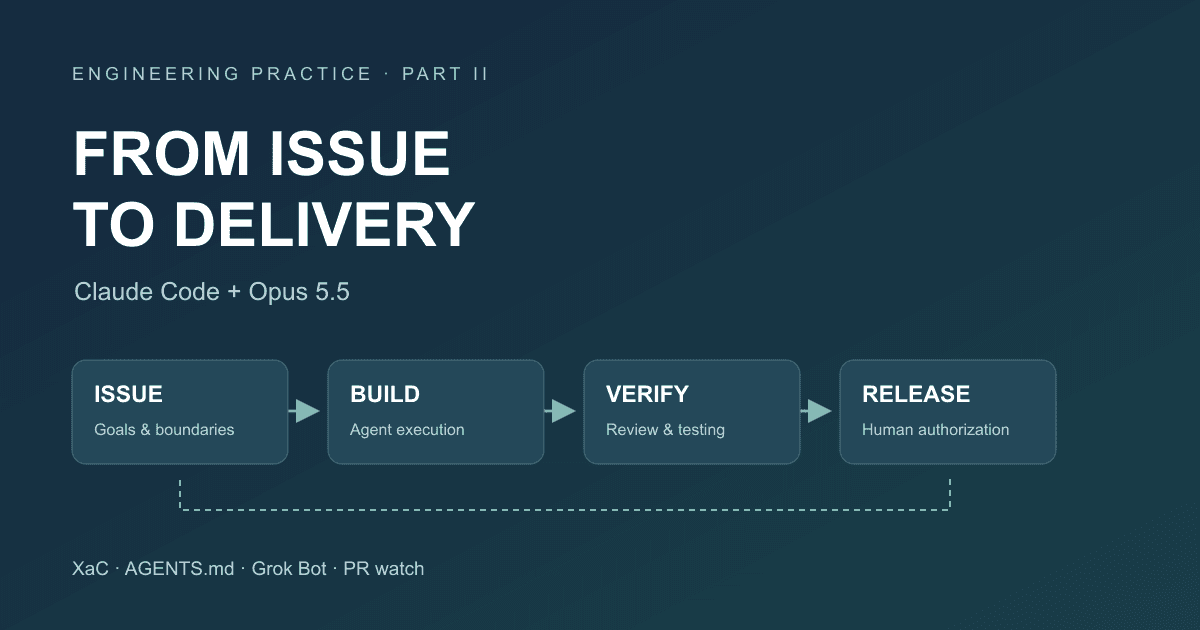
A year after leaving my previous employer, I document the delivery workflow for our financial business that we built around Claude Code and Opus 5.5: XaC, progressive rules, independent review and testing by Grok Bot, PR watch, and our actual delivery over the past three months.
Anthropic Subagent: The Multi-Agent Architecture Revolution
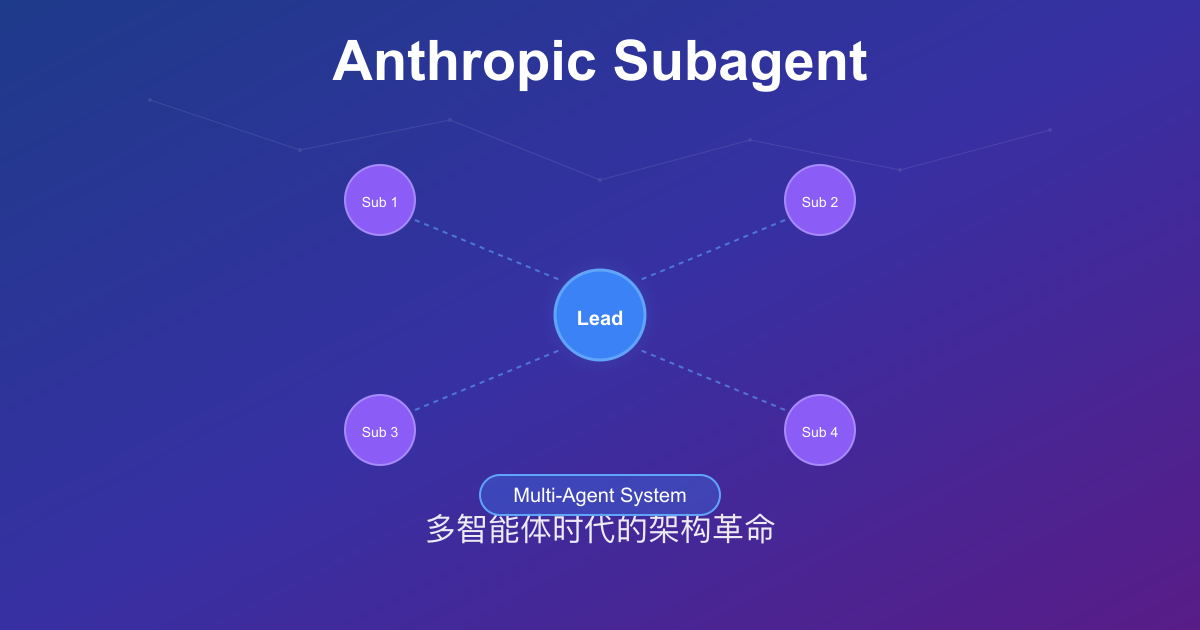
Deep dive into Anthropic multi-agent architecture design. Learn how Subagents break through context window limitations, achieve 90% performance improvements, and real-world applications in Claude Code.