

Hermes 2 Pro - Llama-3 8B is a model from NousResearch. Its Hugging Face model card calls it an upgraded, retrained version of Nous Hermes 2, built on NousResearch/Meta-Llama-3-8B. It adds structured function calling and JSON output to a general chat model, and ships as open weights with GGUF builds for local use.
Key Features
- Training data: a cleaned version of the teknium/OpenHermes-2.5 dataset plus an in-house function-calling and JSON mode dataset.
- Prompt format: ChatML, with a
tool_usechat template for function calling. Tags such as<tool_call>and<tool_response>are single tokens to make streaming parsing easier. - Function calling: according to the card, 90% on a function-calling evaluation built with Fireworks.AI.
- JSON structured output: 84% on a structured JSON output evaluation, per the card. Both are vendor-reported results.
- Reported benchmarks: GPT4All average 72.62, AGIEval average 42.44, BigBench average 43.55, and TruthfulQA mc1 0.410 and mc2 0.578, according to the card.
- Local use: GGUF builds are available, and the card says 4-bit inference needs about 5GB of VRAM. The card recommends LM Studio for chat without function calling.
License and Credits
The model uses the Llama 3 license. The card credits Teknium, interstellarninja, theemozilla, karan4d, and huemin_art, and describes the work as a collaboration between Nous Research, interstellarninja, and Fireworks.AI. The card does not state a release date, so none is given here.
Use Cases
- Local assistants that need tool calls in a predictable tag format.
- Pipelines that require JSON output from a small model.
- Fine-tuning experiments starting from an instruction-tuned Llama 3 8B.
Limitation: this is an 8B model from the Llama 3 generation, so test its quality and context handling on your own tasks before choosing it over newer small models.
Getting Started
- Open the model card and read the prompt format section.
- Load the model with Hugging Face
transformers, or use a GGUF build in a local runner. - For tools, use the
tool_usechat template and the separate function-calling code the card links to on GitHub.
FAQ
What is Hermes 2 Pro Llama-3 8B based on?
NousResearch/Meta-Llama-3-8B, retrained from Nous Hermes 2 data with function-calling additions.
Does it support function calling and JSON mode?
Yes. The card reports 90% on a function-calling eval and 84% on a JSON structured-output eval.
What prompt format does it use?
ChatML, with a tool_use template for tools.
How much memory does it need?
About 5GB of VRAM for 4-bit use, per the card.
Alternatives
- Hermes 3 405B Instruct: another Hermes model in this catalog.
- Llama 3 8B Instruct: Meta's own instruct model on the same base.
- Llama 3.1 8B Instruct: the next Llama generation at 8B.
Conclusion
Hermes 2 Pro Llama-3 8B is a compact open model with built-in tool-call formatting. Start from the model card and compare more options in the models category.
Comments
No comments yet. Be the first to comment!
Related Tools


Related Insights
Grok Bot and Hermes Bot: one person finally gets a think tank and a secretariat
Grok Bot now ships with Cursor Pro+. Hermes Bot runs on a VPS. They are not smarter chat boxes. The think tank advises, the secretariat executes, and you still make the call.

Point Codex at any model with magpie
Install magpie, add a local or signed-in provider, then switch Codex to that model. Rechecked against official magpie docs on 2026-10-06.
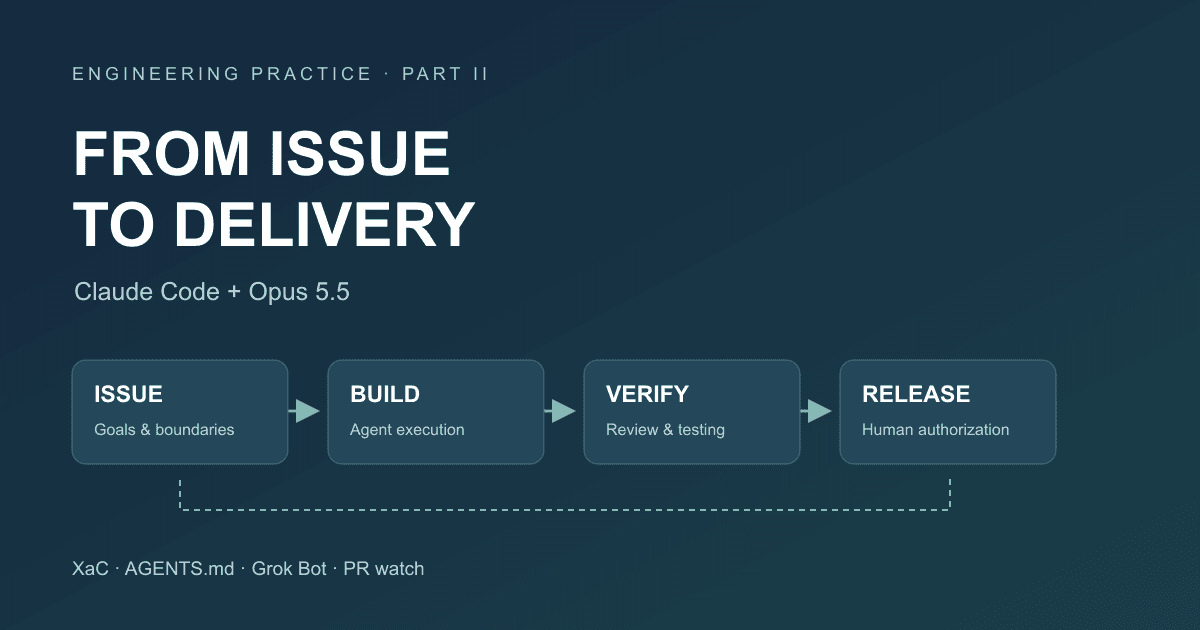
After Code Stopped Being Scarce (Part II): From AI Writing Code to AI Taking Part in Delivery
A year after leaving my previous employer, I document the delivery workflow for our financial business that we built around Claude Code and Opus 5.5: XaC, progressive rules, independent review and testing by Grok Bot, PR watch, and our actual delivery over the past three months.