

deepseek-vl-7b-base
DeepSeek-VL-7B-Base is an open-source vision-language model from DeepSeek, published on Hugging Face as deepseek-ai/deepseek-vl-7b-base. The model card describes it as "designed for real-world vision and language understanding applications". It is a 7B-parameter base model, not a chat model, and belongs to the DeepSeek-VL series, whose associated paper dates from March 2024. The repository is still online and publicly downloadable as of October 29, 2026.
Key Features
- Hybrid vision encoder: SigLIP-L combined with SAM-B, accepting 1024 x 1024 images.
- Language backbone: DeepSeek-LLM-7B-Base, trained on about 2 trillion text tokens. According to the card, the full model then trained on about 400 billion vision-language tokens.
- Base checkpoint: this is the pretrained version. The card describes a separate chat variant in the same series.
- Licensing: code under the MIT license; the model weights under the DeepSeek Model License, which the card says supports commercial use. Read the license text before deploying.
- Format: 7B parameters, F16 Safetensors.
Use Cases
- Research on image understanding and image-grounded language modeling.
- A starting point for fine-tuning a small vision-language model on your own data.
- Prototyping image-and-text pipelines on a single GPU.
Limitation: the card gives no context length and no hosted provider; as of October 29, 2026 no Hugging Face Inference Provider serves it, so you run it yourself.
Pricing and availability
The weights are free to download from Hugging Face. There is no first-party hosted price. For DeepSeek's current API models see DeepSeek V4 Flash and DeepSeek V4 Pro.
Getting Started
- Clone the DeepSeek-VL GitHub repository referenced on the model card (Python 3.8 or later) and run
pip install -e .. - Load the model with
VLChatProcessorandMultiModalityCausalLM, then run inference on image-text conversations, or use the card'scli_chat.pyscript. - A shorter Transformers snippet is also shown on the card.
FAQ
Is DeepSeek-VL-7B-Base free for commercial use?
The card says the DeepSeek-VL series supports commercial use under the DeepSeek Model License, with code under MIT. Review the license before shipping.
What is its base language model?
DeepSeek-LLM-7B-Base.
What image size does it support?
1024 x 1024, through its hybrid SigLIP-L and SAM-B encoder.
Is there a newer DeepSeek vision model?
The catalog lists DeepSeek V4 Flash Vision Exp, which is a different, newer line.
Alternatives
- DeepSeek V4 Flash: DeepSeek's current small hosted model.
- DeepSeek V4 Flash Vision Exp: a newer experimental vision entry.
- DeepSeek V4 Pro: the larger current model.
Conclusion
DeepSeek-VL-7B-Base is a compact, openly licensed vision-language base model, useful for research and fine-tuning. For hosted production use, look at DeepSeek's newer models. See more in the models category.
Sources
Comments
No comments yet. Be the first to comment!
Related Tools

Related Insights

Point Codex at any model with magpie
Install magpie, add a local or signed-in provider, then switch Codex to that model. Rechecked against official magpie docs on 2026-10-06.
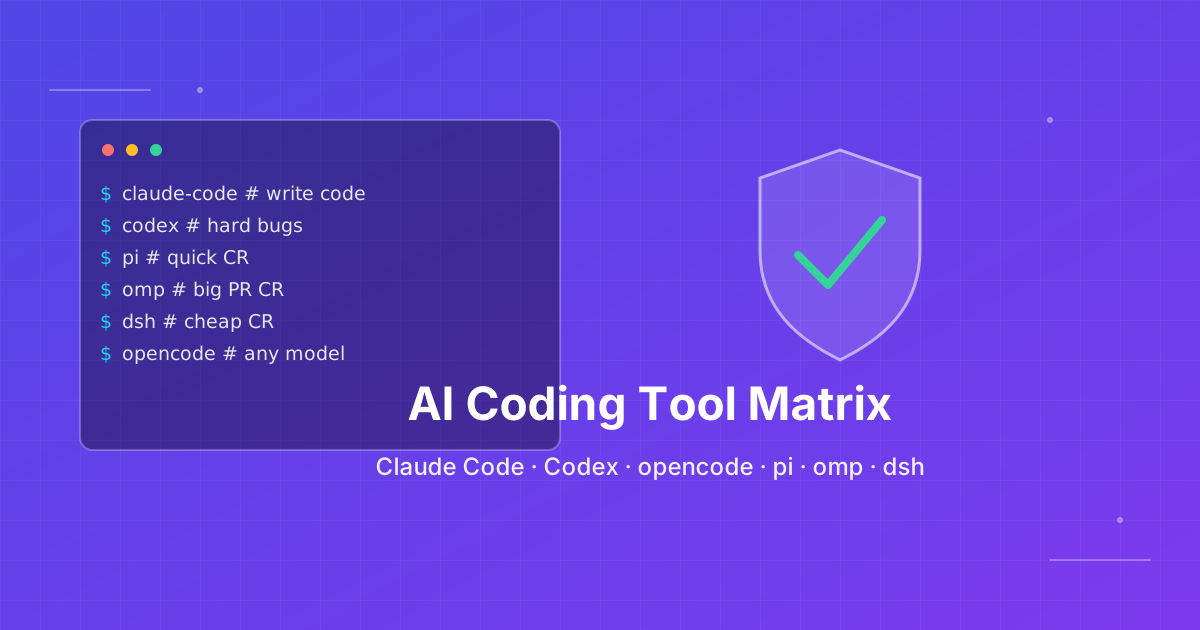
How to pick an AI coding CLI for your repo
Match Claude Code, Codex CLI, OpenCode, Pi, omp, DeepSeek Harness, and Grok Build to the work you actually run. Docs rechecked 2026-10-06.
Running low on ChatGPT Codex quota? Switch to DeepSeek or Grok inside Codex
Codex Router lets you keep your Codex workspace while using DeepSeek, Grok, and other external models. A plain-English guide to routing, quotas, and network access.