
AI models compared (2026)
Model pages here are product cards, not benchmarks we invented. GPT and Claude still dominate coding and agents. Gemini is the default inside Google. Grok is xAI. DeepSeek is the open-weight name people actually deploy. Open a card for the live model ID and the vendor price page. Do not treat a directory blurb as an eval.
View rankingsBrowse alternativesBrowse by tags
Which model is best for coding?
It moves every quarter. Check Claude, GPT, and the current Gemini flash/pro pair on their vendor pages, then run your own repo task. This hub will not freeze a leaderboard.
Open-weight vs API?
APIs are simpler. Open-weight (DeepSeek, Llama, Qwen, Gemma) is for when you need to run it yourself. Cost is hardware plus ops, not a $20 seat.
Where is pricing?
Always the vendor. OpenAI, Anthropic, Google, xAI, and DeepSeek each publish their own tables. We link them. We do not invent cents-per-token.
All AI models compared (2026) tools (223)
Open any tool below for details, features, and pricing.
 Agnes-3.0-FlashAgnes-3.0-Flash Preview is an Apache-2.0 33B multimodal open…
 Claude 3.5 SonnetClaude 3.5 Sonnet, Anthropic's June 2024 model with a 200K c…
- Claude 3 HaikuClaude 3 Haiku (claude-3-haiku-20240307) was Anthropic's sma…
- Claude 3 OpusClaude 3 Opus (claude-3-opus-20240229) is a retired Anthropi…
- Claude 3 SonnetClaude 3 Sonnet (claude-3-sonnet-20240229) was retired from…
- Claude Opus 4.5Anthropic's previous Opus snapshot: 200k context, $5/$25 per…
- Claude Sonnet 4.5Anthropic's previous Sonnet snapshot: 200k context, $3/$15 p…
- Claude v1Claude v1 is Anthropic's first-generation API model line (cl…
 LensVLM-9BApple's 9B vision-language model reads documents as compress…
 AREX-2BAAI's AREX-2 is a 27B open-weight Apache-2.0 agent model th…
 Bespoke NimbleBespoke Labs' open-weight 9B model and training recipe that…
 BGE-M3BGE-M3 is BAAI's open multilingual embedding model: MIT lice…
 BAAI bge-reranker-v2.5-gemma2-lightweightBAAI bge-reranker-v2.5-gemma2-lightweight is a roughly 9B mu…
 Breeze TTS 2Open-weight multilingual TTS from BreezeBlue, built for real…
- Claude Fable 5.1Anthropic's generally available Fable-class model for coding…
- Claude Fable 5Anthropic's Mythos-class flagship made safe for general use,…
- Claude Haiku 4.5Claude Haiku 4.5 is Anthropic's October 2025 small model: $1…
- Claude Haiku 5.5Anthropic's fast, low-cost Claude model for high-volume summ…
- Claude Mythos 5.1Anthropic's most capable model for cybersecurity and biology…
- Claude Opus 4.6Anthropic's most capable hybrid reasoning model: 1M-token co…
- Claude Opus 5.5Anthropic Claude Opus 5.5: Fable-5.1-level intelligence at $…
- Claude Opus 5Anthropic's frontier Opus model with 1M-token context and ef…
- Claude Sonnet 5.5Claude Sonnet 5.5 is Anthropic's mid-tier model from Septemb…
- Claude Sonnet 5Claude Sonnet 5 is Anthropic's legacy mid-tier model, releas…
 cogvlm-base-490-hfcogvlm-base-490-hf is an open CogVLM-17B vision-language che…
 Cohere Command A+Command A+ is Cohere's first mixture-of-experts flagship: 21…
- Cohere: Command ACohere Command A is a 111B-parameter enterprise model with a…
- Cohere: Command RCohere Command R is a 35B, 128K-context model for RAG and to…
- Cohere Embed v3Cohere Embed v3 is a set of four text and image embedding mo…
- Cohere Rerank 3.5Cohere Rerank 3.5 (rerank-v3.5), released December 2, 2024,…
 OpenAI: dall-e-2DALL-E 2 (dall-e-2) was OpenAI's text-to-image model with in…
- OpenAI: dall-e-3Deprecated OpenAI image model from November 2023. Removed fr…
 Deepgram Nova-2Deepgram Nova-2 is a previous speech-to-text model, still li…
 DeepSeek-Coder-V2.5DeepSeek never shipped a model named Coder-V2.5; DeepSeek-V2…
- DeepSeek-R1DeepSeek-R1 is a 671B-parameter reasoning model (37B active…
- DeepSeek V2.5DeepSeek-V2.5, released September 5, 2024, merges DeepSeek-V…
- DeepSeek V3DeepSeek V3 is a 671B-parameter Mixture-of-Experts model (37…
- DeepSeek-V4.1-FlashDeepSeek-V4.1-Flash is a MIT 552B multimodal MoE with 8B/16B…
 DeepSeek-V4-Flash-Vision-ExpDeepSeek-V4-Flash-Vision-Exp is the first V4 multimodal expe…
- DeepSeek V4 FlashDeepSeek small agent model: 284B/13B MoE, 1M context, MIT we…
- DeepSeek V4 Pro 0813DeepSeek flagship 1.6T MoE with 49B active, 1M context, MIT…
- DeepSeek V4DeepSeek V4 is the anticipated next flagship DeepSeek model…
- deepseek-vl-7b-baseDeepSeek-VL-7B-Base is an open 7B vision-language model with…
 DFlash 2Inco AI's Apache 2.0 block-diffusion drafter for speculative…
 Dream-1Dream Labs' World Action Model API for controlling compatibl…
 ElevenLabs Turbo v2.5ElevenLabs Turbo v2.5 (eleven_turbo_v2_5) is a deprecated lo…
 EmbeddingGemmaLightweight multilingual text embedding model from Google De…
 Ember-1Fireworks Research rebuilt Kimi K3 to think less: same bench…
 Flux.1 Dev2024 BFL open-weight stills. Not fully MIT, not the flagship…
- Flux.1 ProPrevious BFL image SKU. Not a 2024 Midjourney/DALL-E 3 crown…
 FLUX 3Black Forest Labs multimodal model for video, audio, upcomin…
 Gemini 2.0 Flash ThinkingGemini 2.0 Flash Thinking was Google's experimental reasonin…
- Gemma 4 26B A4BGoogle DeepMind's open-weight 25.2B MoE model with 3.8B acti…
 GLM-4.7An open-source multilingual multimodal chat model from Zhipu…
- GLM-5.2Zhipu's June 2026 744B MoE coding model with 1M context and…
- GLM-5.3-FlashZhipu's first natively multimodal GLM (confirmed as the 'Ox…
- GLM-5.3Zhipu coding model on GLM Coding Plan. Token API not on the…
- Google: Gemini 1.5 Flash-8BGemini 1.5 Flash-8B is Google's smaller, cheaper Gemini 1.5…
- Google: Gemini 2.0 FlashGemini 2.0 Flash was shut down in the Gemini API on June 1,…
- Google: Gemini 3.1 Flash-LiteGemini 3.1 Flash-Lite (gemini-3.1-flash-lite) is a stable Go…
- Google: Gemini 3.1 Flash LiveGemini 3.1 Flash Live is a legacy audio-to-audio Live API pr…
- Google: Gemini 3.1 Flash TTSGemini 3.1 Flash TTS (gemini-3.1-flash-tts-preview) is a leg…
- Google: Gemini 3.1 ProGemini 3.1 Pro Preview (gemini-3.1-pro-preview) is Google's…
- Google: Gemini 3.5 Flash-LiteGemini 3.5 Flash-Lite is Google's low-cost multimodal model…
- Google: Gemini 3.5 FlashGoogle's agent-first frontier model: long-horizon agentic ta…
- Google: Gemini 3.5 Live TranslateGemini 3.5 Live Translate (gemini-3.5-live-translate-preview…
- Google: Gemini 3.6 FlashGemini 3.6 Flash (gemini-3.6-flash) is Google's stable previ…
- Google: Gemini 3.7 FlashGoogle's most capable Flash model for agentic workflows and…
- Google: Gemini 3.8 Flash TTSGemini 3.8 Flash TTS designs custom voices from a prompt, re…
- Google: Gemini 3 FlashGoogle's latest frontier model delivering breakthrough intel…
- Google: Gemini 3 ProGemini 3 Pro Preview (gemini-3-pro-preview), released Nov 18…
- Google: Gemini 4 ArgonGoogle's new frontier model for long-horizon coding, enterpr…
- Google: Gemini 4 CarbonGoogle's Gemini 4 Carbon is a frontier model for long-horizo…
- Google: Gemini Flash 1.5Gemini 1.5 Flash (gemini-1.5-flash) was Google's fast multim…
- Google: Gemini Nano Banana 2 LiteNano Banana 2 Lite (gemini-3.1-flash-lite-image) is Google's…
- Google: Gemini Omni FlashGemini Omni Flash (gemini-omni-1.1-flash) is Google's video…
- Google: Gemini Pro 1.5Gemini 1.5 Pro, announced February 15, 2024, was a mixture-o…
- Google: Gemma 2 27BGemma 2 27B is Google's open-weights 27B decoder-only text m…
- Google: Gemma 2 9BGemma 2 9B is Google's open-weights 9B text model released J…
- GPT-5.6 LunaOpenAI GPT-5.6 Luna (gpt-5.6-luna) is a low-cost high-volume…
- GPT-5.6 TerraOpenAI GPT-5.6 Terra: balanced daily driver in the 5.6 famil…
- GPT-5.2OpenAI's previous frontier model: 400k context, 128k max out…
- GPT-5.6 SolOpenAI frontier flagship GPT-5.6 Sol: 1.05M context, effort…
- GPT-6.1 SolOpenAI GPT-6.1 Sol: near-Astra intelligence for coding, comp…
- GPT-6.1 TerraOpenAI GPT-6.1 Terra is a lower-cost model for visual reason…
- GPT-6 AstraOpenAI flagship GPT-6 Astra: 1.05M context, computer-use SOT…
- GPT-6 LunaOpenAI GPT-6 Luna: the cheapest GPT-6 tier at $0.10/$0.50 pe…
- GPT-6 SolOpenAI GPT-6 Sol: 1.05M context, reasoning up to max effort…
 GPT Image 2OpenAI's latest image generation model for fast, high-qualit…
 IBM Granite 4.2 30BIBM Granite 4.2 30B is an Apache-2.0 dense reasoning LLM wit…
 Grok 4.6SpaceXAI's frontier 1.5T reasoning model with 500K-token con…
- Grok 4.7SpaceXAI's Grok 4.7 flagship for coding and agents: 500K con…
- GrokxAI / SpaceXAI Grok family. Current docs flagship is grok-4.…
 Hy4 previewTencent Hy4 preview is an Apache-2.0 open-weight MoE model w…
 Ideogram 2.0Ideogram 2.0 launched on August 21, 2024 as Ideogram's text-…
 Index-TranslateBilibili's open multilingual translation family: 150-languag…
 JevJev is TypeSafe's System One model for typed software decisi…
 Jina Embeddings v4Jina Embeddings v4 is a 4B-parameter multimodal, multilingua…
- Jina AI Reranker v3Jina Reranker v3 is a 0.6B listwise multilingual reranker wi…
 K2-Horizon-7BK2-Horizon-7B is an open-weight IFM language model with a 51…
 KAT-Coder V2.5Kwaipilot's open-weight agentic coding model: 35B MoE, 3B ac…
 Kimi K3Moonshot AI's open-weight 2.8T multimodal agentic model with…
 Kolibri-1Aleph Alpha’s open-weight reasoning model for German and Eng…
 Laguna S 2.1Poolside's open-weight 118B MoE coding model with 8B active…
 LFM 2.5-2.6BLiquid AI's open-weight 2.6B dense model trained for on-devi…
 LFM2.5-24B-A2BLiquid AI's open-weight 24B reasoning MoE with 2.45B active…
 LFM3-1.7BLiquid AI's open-weight 1.73B text model for local agents, t…
 Ling-3.0-flash-VLLing-3.0-flash-VL is inclusionAI's MIT multimodal MoE: 124B…
 Ling-3.0-flashLing-3.0-flash is inclusionAI's MIT-licensed hybrid reasonin…
 Ling-3.0-tinyLing-3.0-tiny is inclusionAI's MIT hybrid-linear MoE: 7.9B t…
- Liquid d1-3BLiquid AI's 3B multimodal decision model for calibrated clas…
 Llama 3.1 Euryale 70B v2.2Euryale v2.2 is Sao10K's Llama 3.1 70B finetune for roleplay…
- Llama 3 Euryale 70B v2.1Llama 3 Euryale 70B v2.1 is Sao10K's roleplay-oriented 70B L…
 LLaMA Guard 3Llama Guard 3 is Meta's Llama 3.1-based safety classifier th…
- llava-v1.6-34b-hfllava-v1.6-34b-hf is the Hugging Face Transformers port of L…
 LongCat 2.0Meituan's open-weight MoE model: 1.6T total / ~48B active pa…
 Mercury 2.5Inception's diffusion LLM: 260K context, parallel token gene…
 Mercury 2Inception's diffusion reasoning model: 128K context, paralle…
- CodeLlama 34B InstructCode Llama 34B Instruct is Meta's 34B instruction-tuned code…
- Llama 3.1 405B InstructLlama 3.1 405B Instruct is Meta's July 23, 2024 open-weights…
- Llama 3.1 70B InstructMeta Llama 3.1 70B Instruct, released July 23, 2024, is a 70…
- Llama 3.1 8B InstructLlama 3.1 8B Instruct is Meta's July 23, 2024 instruction-tu…
- Llama 3.2 1B InstructLlama 3.2 1B Instruct is Meta's 1.23B-parameter multilingual…
- Meta Llama 3.2 Vision2024 Llama 3.2 vision snapshot. Not the 2026 multimodal defa…
- Llama 3 70B InstructMeta Llama 3 70B Instruct, released April 18, 2024, is a 70B…
- Llama 3 8B InstructLlama 3 8B Instruct is Meta's 8B instruction-tuned chat mode…
- Llama v2 70B ChatLlama 2 70B Chat is Meta's July 2023 open-weights chat model…
 Midjourney V6Midjourney V6, released December 20, 2023, was the default v…
 MiMo-V2.6Xiaomi's MiMo-V2.6 open-weights series pairs a 1.02T-paramet…
 mini-AGImini-AGI is a byte-level model that trains from scratch on a…
 MiniCPM5-2BOpenBMB MiniCPM5-2B is a dense 2B on-device LLM with 131k co…
 MiniMax H3MiniMax open multimodal video model (July 31, 2026): text/im…
 MiniMax M2.1Open-source 230B parameter MoE model optimized for multi-lan…
 MiniMax M3.1 FlashMiniMax's API model for coding, agentic workflows and comput…
- MiniMax M3MiniMax open-weight frontier model (June 1, 2026): 1M-token…
- MiniMax-Music3MiniMax-Music3 is an open-weight music model that creates fu…
 Mistral Large 4Mistral Large 4 is an open-weight multimodal MoE model for c…
- Mistral: Mistral 7B InstructMistral 7B Instruct is the instruct-tuned version of Mistral…
- Mistral: Mistral NemoMistral Nemo 12B (open-mistral-nemo-2407) is an Apache 2.0 m…
- Mistral Nemo Inferor 12BMN-12B-Inferor-v0.0 is a community 12B merge by Infermatic A…
- Mistral OCR 4.1Mistral OCR 4.1 is Mistral's document OCR service from July…
- Mistral Pixtral 12B2024 Mistral 12B vision snapshot. Not the first-and-only mul…
- Mistral Shieldstral 1.0Mistral Shieldstral 1.0 is a compact multimodal safety class…
- Mistral SmallMistral Small v24.09 (mistral-small-2409) is a 22B model wit…
- Mistral TinyMistral Tiny was the API name for Mistral 7B, renamed open-m…
- Mistral Voxtral Mini Transcribe 2Mistral Voxtral Mini Transcribe 2 (voxtral-mini-2602) is a t…
- Mistral Voxtral Mini Transcribe RealtimeVoxtral Mini Transcribe Realtime is Mistral's open-weight li…
- Mistral Voxtral TTSMistral Voxtral TTS (v26.03) is a text-to-speech model with…
 Muse GlimmerMeta's open-weight 30B agentic multimodal model distilled fr…
- Muse Spark 1.2Meta's coding-focused flagship model powering Muse Code: 1M…
 Muse Spark OpenMeta's open-weight, multimodal MoE for coding and agents, wi…
 mixedbread ai mxbai-rerank-large-v1mxbai-rerank-large-v1 is mixedbread ai's 0.4B English rerank…
 MythoMax 13BMythoMax-L2-13b is Gryphe's Llama 2 13B merge of MythoLogic-…
 Nex-N2.5-miniNex-N2.5-mini is Nex-AGI's Apache-2.0 multimodal agent model…
 Nex-N2.5-ProNex-N2.5-Pro is Nex-AGI's Apache-2.0 multimodal agent checkp…
 Nous: Hermes 3 405B InstructHermes 3 405B is Nous Research's full-parameter fine-tune of…
- NousResearch: Hermes 2 Pro - Llama-3 8BHermes 2 Pro Llama-3 8B is NousResearch's open-weights fine-…
 NV-Embed-v2NV-Embed-v2 is NVIDIA's 2024 embedding model for retrieval w…
- NVIDIA nv-rerankqa-mistral-4b-v3NVIDIA nv-rerankqa-mistral-4b-v3 is a 2024 question-answerin…
- NVIDIA: Llama 3.1 Nemotron 70B InstructLlama 3.1 Nemotron 70B Instruct is NVIDIA's RLHF-tuned Llama…
- NVIDIA Nemotron 3.5 Lightning 30B A3BNVIDIA's efficient open-weight 30B MoE hybrid model with 3B…
- omni-moderation-latestomni-moderation-latest is OpenAI's free moderation model: it…
- OpenAI: GPT-4o-miniGPT-4o mini (gpt-4o-mini-2024-07-18) has a 128K context and…
- OpenAI: GPT-4oGPT-4o (gpt-4o) is OpenAI's multimodal model at $2.50/$10 pe…
- OpenAI: o1-miniOpenAI o1-mini was a low-cost reasoning model with 128k cont…
- OpenAI: o1-previewOpenAI o1-preview (o1-preview-2024-09-12) was shut down on J…
- Shap-eShap-E is OpenAI's open-source MIT-licensed research model t…
 OpenChat 3.5 7BOpenChat 3.5 7B (0106) is an Apache 2.0 chat model fine-tune…
 OrukeetOrukeet is a 25-language ASR model that freezes fitted Gabor…
 PeacebellPeacebell is a small English language model project focused…
 Qwen 4Alibaba's next-generation Qwen 4 flagship is in training, wi…
- Qwen-Audio-3.1Alibaba's Qwen-Audio-3.1 stack adds ASR-Next and TTS-Next, w…
 Qwen-Drive-1.0-4BQwen-Drive-1.0-4B is Alibaba's Apache-2.0 driving VLM that u…
 Qwen-Image-2.1Qwen-Image-2.1 is Alibaba's 7B open-weights model that both…
- Qwen-VLQwen-VL is Alibaba Cloud's 2023 vision-language model on Qwe…
- Qwen2.5 72B InstructPrevious Qwen2.5 72B Instruct snapshot. Not a 2026 latest se…
- Qwen2.5-72BQwen2.5-72B is Alibaba's September 2024 dense LLM snapshot,…
- Qwen2.5 Coder 32B InstructPrevious Qwen2.5-Coder 32B Instruct snapshot. Not the latest…
- Qwen2.5-Coder-32BQwen2.5-Coder-32B is Alibaba's Apache 2.0 base code model (3…
- Qwen2-VL 72B InstructQwen2-VL-72B-Instruct is Alibaba's 72B vision-language model…
- Qwen3.8-2.4T-A95BAlibaba Qwen3.8 2.4T MoE with 95B active, 1M context, multim…
- Qwen3.8-27BAlibaba's open-weight 27B dense companion to Qwen3.8-Max: Ap…
- Qwen3.8-Flash-NextAlibaba's open-weight architecture preview of Qwen4: 125B mu…
- Qwen3.8-MaxAlibaba's 2.4T-parameter open-weight flagship: 95B active Mo…
- Qwen3.8-Omni-FlashQwen3.8-Omni-Flash is Alibaba's omni-modal agentic model: 1M…
- Qwen3-EmbeddingQwen3-Embedding is Alibaba Qwen's Apache 2.0 text embedding…
- Qwen3-VL-EmbeddingQwen3-VL-Embedding is Qwen's Apache-2.0 multimodal embedding…
- Qwen3-VL-RerankerQwen3-VL-Reranker is Alibaba Qwen's Apache 2.0 multimodal re…
- QwQ-32B-PreviewQwQ-32B-Preview is Qwen's experimental 32B reasoning model f…
 Realtime-VenusRealtime-Venus is an Apache 2.0 9B full-duplex audio-visual…
 Recursive FlintRecursive's Apache-2.0 39.8B MoE coding-agent model, with ab…
 Reflection Beam 1.0Reflection AI's Apache-2.0 open-weight 501B MoE for coding a…
- rerank-english-v3.0rerank-english-v3.0 is Cohere's English-only reranking model…
- rerank-multilingual-v3.0Cohere rerank-multilingual-v3.0 is a 4k-context multilingual…
- Cohere: rerank-v3.5Cohere rerank-v3.5 is a multilingual reranking model announc…
 Rocinante 12BRocinante 12B is TheDrummer's 12B fine-tune for roleplay and…
 sanoTTSTiny neural TTS from 294k to 2.3M parameters. Runs in the br…
 Seedance 2.5ByteDance Seed's audio-video model for 30-second storytellin…
 Upstage: Solar Mini 4Upstage's 35B mixture-of-experts model with 3B active parame…
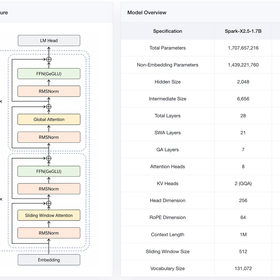 Spark-X2.5-4BSpark-X2.5-4B is XHToken's compact Apache-2.0 open-weight mo…
 Stable Diffusion 3.5Stability 2024 stills family. Homepage also leads with audio…
 StepAudio 3 GenStepAudio 3 Gen creates voices, dialogue, sound effects, and…
 Supra2-IMGSupra2-IMG is an Apache-2.0, 104M-parameter text-to-image Di…
 Swift-Qwen3.8-27BSwift-Qwen3.8-27B is UkisAI's reasoning-efficient Qwen3.8-27…
 Ternary Bonsai 2Ternary Bonsai 2 is a 27B Qwen3.8 ternary GGUF that the mode…
- text-embedding-3-largetext-embedding-3-large is OpenAI's most capable embedding mo…
- text-embedding-3-smallOpenAI text-embedding-3-small is an embedding model with 153…
- text-embedding-ada-002Previous OpenAI embedding snapshot. Not the 2026 embedding d…
- text-moderation-latesttext-moderation-latest was OpenAI's text-only moderation mod…
 Tiel-Coder 35B A3BTiel-Coder 35B A3B is a community agentic coding MoE model b…
- OpenAI: tts-1-hdOpenAI tts-1-hd is a text-to-speech model optimized for qual…
- OpenAI: tts-1Hosted OpenAI tts-1 snapshot. Not the 2026 default TTS path.
 VonVon is an Apache-2.0 395M System One decision model that ans…
 voyage-3-largevoyage-3-large is Voyage AI's general-purpose multilingual e…
 Voyage AI Rerank 2Voyage AI rerank-2 is a second-generation multilingual reran…
 WeLM-617BWeChat AI's 617B MoE model with 23B active parameters, demon…
 WeMM-EmbeddingWeMM-Embedding is Tencent WeChat Vision's multimodal embeddi…
- OpenAI: whisper-1Hosted OpenAI whisper-1 snapshot. Not the 2026 default STT p…
- Whisper V3Whisper large-v3 is OpenAI's open-weight speech recognition…
 WizardLM-2 7BWizardLM-2 7B is a Microsoft WizardLM team chat model fine-t…
- WizardLM-2 8x22BWizardLM-2 8x22B is the largest of three open WizardLM-2 mod…
- xAI: Grok BetaGrok Beta was the provisional name of xAI's first API model,…
 YuE2-3BYuE2-3B is M·A·P's CC BY-NC music model that plans an editab…