
AI models compared (2026)
Model pages here are product cards, not benchmarks we invented. GPT and Claude still dominate coding and agents. Gemini is the default inside Google. Grok is xAI. DeepSeek is the open-weight name people actually deploy. Open a card for the live model ID and the vendor price page. Do not treat a directory blurb as an eval.
View rankingsBrowse alternativesBrowse by tags
Which model is best for coding?
It moves every quarter. Check Claude, GPT, and the current Gemini flash/pro pair on their vendor pages, then run your own repo task. This hub will not freeze a leaderboard.
Open-weight vs API?
APIs are simpler. Open-weight (DeepSeek, Llama, Qwen, Gemma) is for when you need to run it yourself. Cost is hardware plus ops, not a $20 seat.
Where is pricing?
Always the vendor. OpenAI, Anthropic, Google, xAI, and DeepSeek each publish their own tables. We link them. We do not invent cents-per-token.
All AI models compared (2026) tools (214)
Open any tool below for details, features, and pricing.
 Agnes-3.0-FlashAgnes-3.0-Flash Preview is an Apache-2.0 33B multimodal open…
 Claude 3.5 SonnetPrevious Claude 3.5 Sonnet snapshot. Not the 2026 default.
- Claude 3 HaikuPrevious Claude 3 Haiku snapshot. Not the 2026 fast default.
- Claude 3 OpusPrevious Claude 3 Opus snapshot. Not the 2026 flagship.
- Claude 3 SonnetPrevious Claude 3 Sonnet snapshot. Not the 2026 default.
- Claude Opus 4.5Anthropic's previous Opus snapshot: 200k context, $5/$25 per…
- Claude Sonnet 4.5Anthropic's previous Sonnet snapshot: 200k context, $3/$15 p…
- Claude v1Previous Claude v1 snapshot. Not a 2026 text default.
 LensVLM-9BApple's 9B vision-language model reads documents as compress…
 AREX-2BAAI's 27B open-weight agent model for long-horizon self-imp…
 Bespoke NimbleBespoke Labs' open-weight 9B model and training recipe that…
 BGE-M32024 BAAI multilingual embedding snapshot. Not a 2026 MIRACL…
 BAAI bge-reranker-v2.5-gemma2-lightweightPrevious BGE reranker v2.5 Gemma2 lightweight snapshot.
 Breeze TTS 2Open-weight multilingual TTS from BreezeBlue, built for real…
- Claude Fable 5.1Anthropic's generally available Fable-class model for coding…
- Claude Fable 5Anthropic's Mythos-class flagship made safe for general use,…
- Claude Haiku 4.5Claude Haiku 4.5: a previous low-cost Claude row at $1/$5 pe…
- Claude Haiku 5.5Anthropic's fast, low-cost Claude model for high-volume summ…
- Claude Mythos 5.1Anthropic's most capable model for cybersecurity and biology…
- Claude Opus 4.6Anthropic's most capable hybrid reasoning model: 1M-token co…
- Claude Opus 5.5Anthropic Claude Opus 5.5: Fable-5.1-level intelligence at $…
- Claude Opus 5Anthropic's frontier Opus model with 1M-token context and ef…
- Claude Sonnet 5.5Anthropic Claude Sonnet 5.5: second model in the Claude 5.5…
- Claude Sonnet 5Claude Sonnet 5: live mid-tier Claude row at $2/$10 per 1M t…
 cogvlm-base-490-hfPrevious CogVLM snapshot. Not a 2026 VLM default.
 Cohere Command A+Command A+ is Cohere's first mixture-of-experts flagship: 21…
- Cohere: Command ACohere Command A: live Command lead on first-party docs. Not…
- Cohere: Command RPrevious Cohere Command R snapshot. Not a 2026 chat / RAG de…
- Cohere Embed v3Previous Cohere embed snapshot. Not a $0.10/1M 2026 default.
- Cohere Rerank 3.5Previous Cohere rerank snapshot.
 OpenAI: dall-e-2Previous OpenAI DALL-E 2 snapshot. DALL-E 3 is already remov…
- OpenAI: dall-e-3Deprecated OpenAI image model from November 2023. Removed fr…
 Deepgram Nova-2Previous Deepgram ASR. Not the fastest 2026 crown.
 DeepSeek-Coder-V2.5Previous DeepSeek coder snapshot. Not a 90.2% HumanEval cens…
- DeepSeek-R1Previous DeepSeek-R1 snapshot. Not an o1 / 2026 reasoning de…
- DeepSeek V2.5Previous DeepSeek V2.5 snapshot. Not a 2026 chat+coder defau…
- DeepSeek V3Previous DeepSeek V3 snapshot. Not a GPT-4o / Claude 3.5 cen…
- DeepSeek-V4.1-FlashDeepSeek-V4.1-Flash is a MIT 552B multimodal MoE with 8B/16B…
 DeepSeek-V4-Flash-Vision-ExpDeepSeek-V4-Flash-Vision-Exp is the first V4 multimodal expe…
- DeepSeek V4 FlashDeepSeek small agent model: 284B/13B MoE, 1M context, MIT we…
- DeepSeek V4 Pro 0813DeepSeek flagship 1.6T MoE with 49B active, 1M context, MIT…
- DeepSeek V4DeepSeek V4 represents the next generation of DeepSeek's fla…
- deepseek-vl-7b-basePrevious DeepSeek-VL 7B Base snapshot. Not a 2026 VL default…
 DFlash 2Inco AI's Apache 2.0 block-diffusion drafter for speculative…
 ElevenLabs Turbo v2.5Previous ElevenLabs Turbo v2.5 snapshot. Not the 2026 voice…
 EmbeddingGemmaLightweight multilingual text embedding model from Google De…
 Ember-1Fireworks Research rebuilt Kimi K3 to think less: same bench…
 Flux.1 Dev2024 BFL open-weight stills. Not fully MIT, not the flagship…
- Flux.1 ProPrevious BFL image SKU. Not a 2024 Midjourney/DALL-E 3 crown…
 FLUX 3Black Forest Labs multimodal model for video, audio, upcomin…
 Gemini 2.0 Flash ThinkingPrevious Gemini 2.0 Flash Thinking snapshot. Not a 2026 o1-m…
- Gemma 4 26B A4BGoogle DeepMind's open-weight 25.2B MoE model with 3.8B acti…
 GLM-4.7An open-source multilingual multimodal chat model from Zhipu…
- GLM-5.2Zhipu's June 2026 744B MoE coding model with 1M context and…
- GLM-5.3-FlashZhipu's first natively multimodal GLM (confirmed as the 'Ox…
- GLM-5.3Zhipu coding model on GLM Coding Plan. Token API not on the…
- Google: Gemini 1.5 Flash-8BPrevious Gemini 1.5 Flash-8B snapshot. Not the 2026 default.
- Google: Gemini 2.0 FlashPrevious Gemini 2.0 Flash snapshot. Live Flash is Gemini 3.7…
- Google: Gemini 3.1 Flash-LiteGoogle Gemini 3.1 Flash-Lite: leftover cheap Flash-Lite sibl…
- Google: Gemini 3.1 Flash LiveGoogle Gemini 3.1 Flash Live: leftover live/audio sibling on…
- Google: Gemini 3.1 Flash TTSGoogle Gemini 3.1 Flash TTS: leftover TTS sibling on the liv…
- Google: Gemini 3.1 ProGoogle Gemini 3.1 Pro: leftover Pro sibling on the live mode…
- Google: Gemini 3.5 Flash-LiteGoogle Gemini 3.5 Flash-Lite: leftover cheap Flash-Lite row…
- Google: Gemini 3.5 FlashGoogle's agent-first frontier model: long-horizon agentic ta…
- Google: Gemini 3.5 Live TranslateGoogle Gemini 3.5 Live Translate: leftover live-translate si…
- Google: Gemini 3.6 FlashGoogle Gemini 3.6 Flash: previous-generation Flash after 3.5…
- Google: Gemini 3.7 FlashGoogle's most capable Flash model for agentic workflows and…
- Google: Gemini 3.8 Flash TTSGemini 3.8 Flash TTS designs custom voices from a prompt, re…
- Google: Gemini 3 FlashGoogle's latest frontier model delivering breakthrough intel…
- Google: Gemini 3 ProPrevious Gemini 3 Pro Preview snapshot. Not a 2026 vision cr…
- Google: Gemini 4 ArgonGoogle's new frontier model for long-horizon coding, enterpr…
- Google: Gemini Flash 1.5Previous Gemini 1.5 Flash snapshot. Not the 2026 default.
- Google: Gemini Nano Banana 2 LiteGoogle Gemini Nano Banana 2 Lite: leftover cheaper Nano Bana…
- Google: Gemini Omni FlashGoogle Gemini Omni Flash: leftover Omni Flash sibling on the…
- Google: Gemini Pro 1.5Previous Gemini 1.5 Pro snapshot. Not the 2026 default.
- Google: Gemma 2 27BPrevious Gemma 2 27B snapshot. Not a 2026 default open model…
- Google: Gemma 2 9BPrevious Gemma 2 9B snapshot. Not a 2026 default small model…
- GPT-5.6 LunaOpenAI GPT-5.6 Luna: fast affordable GPT-5.6 tier, 128k cont…
- GPT-5.6 TerraOpenAI GPT-5.6 Terra: balanced daily driver in the 5.6 famil…
- GPT-5.2OpenAI's previous frontier model: 400k context, 128k max out…
- GPT-5.6 SolOpenAI frontier flagship GPT-5.6 Sol: 1.05M context, effort…
- GPT-6.1 SolOpenAI GPT-6.1 Sol: near-Astra intelligence for coding, comp…
- GPT-6 AstraOpenAI flagship GPT-6 Astra: 1.05M context, computer-use SOT…
- GPT-6 LunaOpenAI GPT-6 Luna: the cheapest GPT-6 tier at $0.10/$0.50 pe…
- GPT-6 SolOpenAI GPT-6 Sol: 1.05M context, reasoning up to max effort…
 GPT Image 2OpenAI's latest image generation model for fast, high-qualit…
 IBM Granite 4.2 30BOpen-weight dense reasoning LLM from IBM: 30B parameters, Ap…
 Grok 4.6SpaceXAI's frontier 1.5T reasoning model with 500K-token con…
- Grok 4.7SpaceXAI's Grok 4.7 flagship for coding and agents: 500K con…
- GrokxAI / SpaceXAI Grok family. Current docs flagship is grok-4.…
 Hy4 previewTencent's next-generation open-weight MoE flagship: 770B tot…
 Ideogram 2.0Ideogram Aug 2024 snapshot. No invented later-version or sea…
 Index-TranslateBilibili's open multilingual translation family: 150-languag…
 JevJev is TypeSafe's System One model for typed software decisi…
 Jina Embeddings v4Previous Jina Embeddings v4 snapshot.
- Jina AI Reranker v3Previous Jina rerank snapshot.
 K2-Horizon-7BK2-Horizon-7B is an open-weight IFM language model with a 51…
 KAT-Coder V2.5Kwaipilot's open-weight agentic coding model: 35B MoE, 3B ac…
 Kimi K3Moonshot AI's open-weight 2.8T multimodal agentic model with…
 Kolibri-1Aleph Alpha’s open-weight reasoning model for German and Eng…
 Laguna S 2.1Poolside's open-weight 118B MoE coding model with 8B active…
 LFM 2.5-2.6BLiquid AI's open-weight 2.6B dense model trained for on-devi…
 Ling-3.0-flash-VLLing-3.0-flash-VL is inclusionAI's MIT multimodal MoE: 124B…
 Ling-3.0-flashinclusionAI MIT hybrid-linear MoE: 124B total, 5.1B active.
 Ling-3.0-tinyLing-3.0-tiny is inclusionAI's MIT hybrid-linear MoE: 7.9B t…
- Liquid d1-3BLiquid AI's 3B multimodal decision model for calibrated clas…
 Llama 3.1 Euryale 70B v2.2Previous Llama 3.1 Euryale 70B v2.2 snapshot. Not a 2026 Lla…
- Llama 3 Euryale 70B v2.1Previous Llama 3 Euryale 70B v2.1 snapshot. Not a 2026 Llama…
 LLaMA Guard 3Previous Llama Guard snapshot. Not the 2026 safety default.
- llava-v1.6-34b-hfPrevious LLaVA-NeXT / LLaVA 1.6 snapshot.
 LongCat 2.0Meituan's open-weight MoE model: 1.6T total / ~48B active pa…
 Mercury 2.5Inception's diffusion LLM: 260K context, parallel token gene…
 Mercury 2Inception's diffusion reasoning model: 128K context, paralle…
- CodeLlama 34B InstructPrevious Code Llama 34B Instruct snapshot. Not a 2026 coding…
- Llama 3.1 405B InstructPrevious Llama 3.1 405B Instruct snapshot. Not a GPT-4o crow…
- Llama 3.1 70B InstructPrevious Llama 3.1 70B Instruct snapshot. Not the 2026 defau…
- Llama 3.1 8B InstructPrevious Llama 3.1 8B Instruct snapshot. Not the 2026 defaul…
- Llama 3.2 1B InstructPrevious Llama 3.2 1B Instruct snapshot. Not a 1.3B typo.
- Meta Llama 3.2 Vision2024 Llama 3.2 vision snapshot. Not the 2026 multimodal defa…
- Llama 3 70B InstructPrevious Llama 3 70B Instruct snapshot. Not the 2026 default…
- Llama 3 8B InstructPrevious Llama 3 8B Instruct snapshot. Not the 2026 default.
- Llama v2 70B ChatPrevious Llama v2 70B Chat snapshot. Not a 2026 chat default…
 Midjourney V6Midjourney V6 snapshot from Dec 2023. Not the current defaul…
 MiMo-V2.6Xiaomi's MiMo-V2.6 open-weights series pairs a 1.02T-paramet…
 mini-AGImini-AGI is a byte-level model that trains from scratch on a…
 MiniCPM5-2BOpenBMB MiniCPM5-2B is a dense 2B on-device LLM with 131k co…
 MiniMax H3MiniMax open multimodal video model (July 31, 2026): text/im…
 MiniMax M2.1Open-source 230B parameter MoE model optimized for multi-lan…
 MiniMax M3MiniMax open-weight frontier model (June 1, 2026): 1M-token…
- MiniMax-Music3MiniMax's open-weight music generation model with studio-gra…
 Mistral Large 4Mistral Large 4 is Mistral's public-preview multimodal MoE m…
- Mistral: Mistral 7B InstructPrevious Mistral 7B Instruct snapshot.
- Mistral: Mistral NemoPrevious Mistral Nemo 12B snapshot. Live catalog is Medium 3…
- Mistral Nemo Inferor 12BPrevious Inferor 12B snapshot. Live catalog is Medium 3.5 /…
- Mistral OCR 4.1Mistral OCR 4.1: live latest OCR with paragraph boxes, struc…
- Mistral Pixtral 12B2024 Mistral 12B vision snapshot. Not the first-and-only mul…
- Mistral Shieldstral 1.0Mistral Shieldstral 1.0: live compact multimodal moderation…
- Mistral SmallPrevious Mistral Small v24.09 snapshot.
- Mistral TinyPrevious Mistral Tiny snapshot. Live catalog is Medium 3.5 /…
- Mistral Voxtral Mini Transcribe 2Mistral Voxtral Mini Transcribe 2: live Premier transcriptio…
- Mistral Voxtral Mini Transcribe RealtimeMistral Voxtral Mini Transcribe Realtime: live realtime tran…
- Mistral Voxtral TTSMistral Voxtral TTS: live catalog TTS row, v 26.03, CC BY-NC…
 Muse GlimmerMeta's open-weight 30B agentic multimodal model distilled fr…
- Muse Spark 1.2Meta's coding-focused flagship model powering Muse Code: 1M…
 mixedbread ai mxbai-rerank-large-v1Previous mxbai-rerank-large-v1 snapshot.
 MythoMax 13BPrevious MythoMax 13B snapshot.
 Nex-N2.5-miniNex-N2.5-mini is Nex-AGI's Apache-2.0 multimodal agent model…
 Nex-N2.5-ProNex-N2.5-Pro is Nex-AGI's Apache-2.0 multimodal agent checkp…
 Nous: Hermes 3 405B InstructPrevious Hermes 3 405B Instruct snapshot. Not a 2026 frontie…
- NousResearch: Hermes 2 Pro - Llama-3 8BPrevious Hermes 2 Pro Llama-3 8B snapshot.
 NV-Embed-v22024 NVIDIA embedding snapshot.
- NVIDIA nv-rerankqa-mistral-4b-v3Previous NVIDIA nv-rerankqa-mistral-4b-v3 snapshot.
- NVIDIA: Llama 3.1 Nemotron 70B InstructPrevious NVIDIA Llama 3.1 Nemotron 70B Instruct snapshot. No…
- NVIDIA Nemotron 3.5 Lightning 30B A3BNVIDIA's efficient open-weight 30B MoE hybrid model with 3B…
- omni-moderation-latestHosted OpenAI omni-moderation snapshot. Not the 2026 safety…
- OpenAI: GPT-4o-miniPrevious GPT-4o mini snapshot. Not the 2026 latest.
- OpenAI: GPT-4oPrevious GPT-4o snapshot. Not the 2026 latest.
- OpenAI: o1-miniPrevious o1-mini snapshot. Not the 2026 reasoning default.
- OpenAI: o1-previewPrevious o1-preview snapshot. Not a cheaper o1 and not 2026…
- Shap-ePrevious OpenAI Shap-E snapshot. Live stills path is GPT Ima…
 OpenChat 3.5 7BPrevious OpenChat 3.5 7B snapshot.
 OrukeetOrukeet is a 25-language ASR model that freezes fitted Gabor…
 PeacebellFrom-scratch English WWII language models at 291M and 148M p…
 Qwen 4Alibaba's next-generation Qwen 4 flagship is in training, wi…
- Qwen-Audio-3.1Alibaba's Qwen-Audio-3.1 stack adds ASR-Next and TTS-Next, w…
 Qwen-Drive-1.0-4BQwen-Drive-1.0-4B is Alibaba's Apache-2.0 driving VLM that u…
 Qwen-Image-2.1Qwen-Image-2.1 is Alibaba's 7B open-weights model that both…
- Qwen-VLPrevious Alibaba Qwen-VL snapshot. Not a 2026 LVLM default.
- Qwen2.5 72B InstructPrevious Qwen2.5 72B Instruct snapshot. Not a 2026 latest se…
- Qwen2.5-72BPrevious Qwen stills LLM. Not a 2026 Llama-3-405B crown.
- Qwen2.5 Coder 32B InstructPrevious Qwen2.5-Coder 32B Instruct snapshot. Not the latest…
- Qwen2.5-Coder-32BPrevious Qwen code snapshot.
- Qwen2-VL 72B InstructPrevious Qwen2-VL 72B Instruct snapshot. Not a 2024 VL crown…
- Qwen3.8-2.4T-A95BAlibaba Qwen3.8 2.4T MoE with 95B active, 1M context, multim…
- Qwen3.8-27BAlibaba's open-weight 27B dense companion to Qwen3.8-Max: Ap…
- Qwen3.8-Flash-NextAlibaba's open-weight architecture preview of Qwen4: 125B mu…
- Qwen3.8-MaxAlibaba's 2.4T-parameter open-weight flagship: 95B active Mo…
- Qwen3.8-Omni-FlashQwen3.8-Omni-Flash is Alibaba's omni-modal agentic model: 1M…
- Qwen3-EmbeddingPrevious Qwen3 embedding snapshot.
- Qwen3-VL-EmbeddingPrevious Qwen3-VL embedding snapshot.
- Qwen3-VL-RerankerPrevious Qwen3-VL rerank snapshot.
- QwQ-32B-PreviewPrevious QwQ-32B-Preview snapshot.
 Realtime-VenusRealtime-Venus is an Apache 2.0 9B full-duplex audio-visual…
- rerank-english-v3.0Previous Cohere English rerank snapshot.
- rerank-multilingual-v3.0Previous Cohere multilingual rerank snapshot.
- Cohere: rerank-v3.5Previous Cohere rerank-v3.5 snapshot.
 Rocinante 12BPrevious Rocinante 12B snapshot.
 sanoTTSTiny neural TTS from 294k to 2.3M parameters. Runs in the br…
 Seedance 2.5ByteDance Seed's audio-video model for 30-second storytellin…
 Upstage: Solar Mini 4Upstage's 35B mixture-of-experts model with 3B active parame…
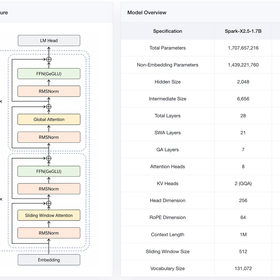 Spark-X2.5-4BXHToken's efficient 4B open-weight model: hybrid sliding-win…
 Stable Diffusion 3.5Stability 2024 stills family. Homepage also leads with audio…
 StepAudio 3 GenStepAudio 3 Gen creates voices, dialogue, sound effects, and…
 Supra2-IMGSupra2-IMG is an Apache-2.0, 104M-parameter text-to-image Di…
 Swift-Qwen3.8-27BSwift-Qwen3.8-27B is UkisAI's reasoning-efficient Qwen3.8-27…
 Ternary Bonsai 2Ternary Bonsai 2 is a 27B Qwen3.8 ternary GGUF that the mode…
- text-embedding-3-large2024 OpenAI embedding snapshot.
- text-embedding-3-smallPrevious OpenAI embedding snapshot. Not a 2026 embedding cro…
- text-embedding-ada-002Previous OpenAI embedding snapshot. Not the 2026 embedding d…
- text-moderation-latestPrevious OpenAI text-moderation snapshot. Not the 2026 safet…
 Tiel-Coder 35B A3BAgentic coding MoE. Not a lab release.
- OpenAI: tts-1-hdHosted OpenAI tts-1-hd snapshot. Not the 2026 default TTS pa…
- OpenAI: tts-1Hosted OpenAI tts-1 snapshot. Not the 2026 default TTS path.
 VonVon is an Apache-2.0 395M System One decision model that ans…
 voyage-3-largeVoyage AI's latest SOTA general-purpose embedding model, ran…
 Voyage AI Rerank 2Previous Voyage rerank snapshot.
 WeLM-617BWeChat AI's 617B MoE model with 23B active parameters, demon…
 WeMM-EmbeddingTencent WeChat Vision's universal multimodal embedding famil…
- OpenAI: whisper-1Hosted OpenAI whisper-1 snapshot. Not the 2026 default STT p…
- Whisper V3Open-weight Whisper large-v3 family. Not OpenAI's current ho…
 WizardLM-2 7BPrevious WizardLM-2 7B snapshot. Do not keep leftover 10x-la…
- WizardLM-2 8x22BPrevious WizardLM-2 8x22B snapshot.
- xAI: Grok BetaPrevious xAI Grok Beta snapshot. Not a 2026 reasoning defaul…
 YuE2-3BYuE2-3B is M·A·P's CC BY-NC music model that plans an editab…